Snowflake
Stream CDC data into Snowflake using Streamkap, with upsert and append ingestion modes, schema evolution, and Snowflake-managed Iceberg tables.
Prerequisites
A Snowflake account granted ACCOUNTADMIN system-defined role or custom role with privileges to:
CREATE WAREHOUSE, DATABASE, SCHEMACREATE ROLE, USERCREATE NETWORK POLICY
Snowflake Setup
It’s recommended to create a separate user and role for Streamkap to access your Snowflake database. Below is an example script that does that.
-- We've provided defaults so, change these as required with names for Database Objects in 'UPPERCASE'
SET user_name           = UPPER('STREAMKAP_USER');
SET user_password       = '{password}'; -- IMPORTANT: Make sure to change this!
SET warehouse_name      = UPPER('STREAMKAP_WH'); -- Used for automatic QA, UPSERT mode and optional views
SET database_name       = UPPER('STREAMKAPDB');
SET schema_name         = UPPER('STREAMKAP');
SET role_name           = UPPER('STREAMKAP_ROLE');
SET network_policy_name = UPPER('STREAMKAP_NETWORK_ACCESS');

-- If your Snowflake account uses custom roles to grant privileges, change these values below
SET sysadmin_role       = UPPER('SYSADMIN');
SET securityadmin_role  = UPPER('SECURITYADMIN');
SET accountadmin_role   = UPPER('ACCOUNTADMIN');

-- Create a warehouse with defaults:
-- Standard, X-Small, No Scaling, Auto-Suspend after 1 Minute
USE ROLE IDENTIFIER($sysadmin_role);
CREATE WAREHOUSE IF NOT EXISTS IDENTIFIER($warehouse_name) AUTO_SUSPEND =1;

-- Create a database and schema for Streamkap
USE WAREHOUSE IDENTIFIER($warehouse_name);
CREATE DATABASE IF NOT EXISTS IDENTIFIER($database_name);
USE DATABASE IDENTIFIER($database_name);
CREATE SCHEMA IF NOT EXISTS IDENTIFIER($schema_name);

-- Create a Snowflake role with privileges for the Streamkap connector
USE ROLE IDENTIFIER($securityadmin_role);
CREATE ROLE IF NOT EXISTS IDENTIFIER($role_name);

-- Grant privileges on the warehouse
GRANT USAGE ON WAREHOUSE IDENTIFIER($warehouse_name) TO ROLE IDENTIFIER($role_name);

-- Grant privileges on the database
GRANT USAGE ON DATABASE IDENTIFIER($database_name) TO ROLE IDENTIFIER($role_name);
-- Optional: Permissions for auto schema creation on the database
GRANT CREATE SCHEMA ON DATABASE IDENTIFIER($database_name) TO ROLE IDENTIFIER($role_name);

-- Grant privileges on the database schema
USE ROLE IDENTIFIER($sysadmin_role);
USE DATABASE IDENTIFIER($database_name);
GRANT USAGE ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
GRANT CREATE TABLE ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
GRANT CREATE FILE FORMAT ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
GRANT CREATE STAGE ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
GRANT CREATE PIPE ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);

-- Grant privileges for dynamic table and task creation (Only if auto-creation is enabled)
GRANT CREATE DYNAMIC TABLE ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
GRANT CREATE TASK ON SCHEMA IDENTIFIER($schema_name) TO ROLE IDENTIFIER($role_name);
USE ROLE IDENTIFIER($accountadmin_role);
GRANT EXECUTE TASK ON ACCOUNT TO ROLE IDENTIFIER($role_name);

-- Create a user for Streamkap
USE ROLE IDENTIFIER($securityadmin_role);
CREATE USER IDENTIFIER($user_name) PASSWORD = $user_password DEFAULT_ROLE = $role_name;

-- Grant the custom role to the Streamkap user
GRANT ROLE IDENTIFIER($role_name) TO USER IDENTIFIER($user_name);

-- Set the custom role as the default role for the Streamkap user.
-- If you encounter an 'Insufficient privileges' error, verify the '$securityadmin_role' has OWNERSHIP privilege on the '$user_name'.
ALTER USER IDENTIFIER($user_name) SET DEFAULT_ROLE = $role_name;

-- Prevents Snowflake getting confused in an edge-case where a table exists in the public schema and current schema with the same name.
ALTER USER IDENTIFIER($user_name) SET SEARCH_PATH = '$current';

-- Allow the Streamkap user access to the Snowflake account
-- Latest IPs can be found here: https://docs.streamkap.com/docs/streamkap-ip-addresses
-- If you need to edit the network policy, you can use:
-- ALTER NETWORK POLICY STREAMKAP_NETWORK_ACCESS SET ALLOWED_IP_LIST=('52.32.238.100');
CREATE NETWORK POLICY IDENTIFIER($network_policy_name) ALLOWED_IP_LIST=('52.32.238.100');
ALTER USER IDENTIFIER($user_name) SET NETWORK_POLICY = $network_policy_name;Key Pair Authentication
The connector relies on an RSA key pair for authentication which you can generate using OpenSSH. Below are example scripts that do that. You can modify them to suit your security policies, but please ensure the key pair meets these minimum requirements:
- RSA 2048-bit
- PKCS#8 key format
# Make sure to change '{passphrase}' to a password of your choice
openssl genrsa 2048 | openssl pkcs8 -topk8 -v2 aes256 -inform PEM -out streamkap_key.p8 -passout pass:{passphrase}

# generates the public key, referencing the private key
# Don't forget to replace '{passphrase}' with the password used in the previous command
openssl rsa -in streamkap_key.p8 -pubout -out streamkap_key.pub -passin pass:{passphrase}
openssl genrsa 2048 | openssl pkcs8 -topk8 -inform PEM -out streamkap_key.p8 -nocrypt
# generates the public key, referencing the private key
openssl rsa -in streamkap_key.p8 -pubout -out streamkap_key.pubThe scripts above should create two files (the key pair), one private (may have an extension e.g. .p8) and the other public (usually has the extension .pub). Store both files in a secure place.
Once generated, the public key needs to be assigned to the Snowflake database user created for Streamkap earlier.
This command will copy the public key you generated to your clipboard.
egrep -v '^-|^$' ./streamkap_key.pub | pbcopyGet-Content .\streamkap_key.pub | Where-Object { $_ -notmatch '^-|^$' } | Set-ClipboardNow attach the public key to the user:
-- We've provided a default, so change this as required
SET user_name = UPPER('STREAMKAP_USER');

USE ROLE SECURITYADMIN;

-- Replace '{public key}' below with the public key file contents
-- If you used the previous command to copy the key to your clipboard, use Ctrl+V (Windows)
-- or Cmd+V (MacOS) to replace the '{public key}' placeholder with the key
-- Key part MUST start with 'MII' excluding any headers and footers
ALTER USER IDENTIFIER($user_name) SET RSA_PUBLIC_KEY = '{public key}';
Streamkap Setup
Follow these steps to configure your new connector:
1. Create the Destination
- Navigate to Add Connectors.
- Choose Snowflake.
2. Connection Settings
-
Name: Enter a name for your connector.
-
Snowflake URL: The URL for accessing your Snowflake account. This URL must include your account identifier. Note that the protocol (
https://) and port number are optional. -
Username: User login name for the Snowflake account (Case sensitive).
-
Private Key: Provide the private key you generated by using the command below.
egrep -v '^-|^$' ./streamkap_key.p8 | pbcopyGet-Content .\streamkap_key.p8 | Where-Object { $_ -notmatch '^-|^$' } | Set-Clipboard- Key secured with passphrase?: If checked (default), provide your SSH key’s passphrase, otherwise, uncheck for SSH keys without passphrase.
- Private Key Passphrase: The passphrase is used to decrypt the private key.
- Key secured with passphrase?: If checked (default), provide your SSH key’s passphrase, otherwise, uncheck for SSH keys without passphrase.
-
Database Name: The name of the database to use (Case sensitive).
-
Schema Name: The name of the schema where tables will be created (Case sensitive).
-
Snowflake Role: The name of an existing role with necessary privileges (for Streamkap) assigned to the user specified by Username (Case sensitive).
3. Ingestion Settings
-
Ingestion Mode: How the Connector loads data into the Snowflake tables. See Upsert mode for further details.
-
appendmode:- Use Dynamic Tables: Specifies whether the connector should create Dynamic Tables & Cleanup Tasks. See Dynamic Tables.
- Custom SQL Template - Dynamic Table Creation: These template queries run for each table the first time a record is streamed for them. Changes are not retroactive for tables that already have a Dynamic Table — see Dynamic Tables for how to force recreation.
- Custom SQL Template - Dynamic Table Name: Can be used as
{{dynamicTableName}}in dynamic table creation SQL. It can use input JSON data for more complex mappings and logic. - Custom SQL Template - Input JSON data: Use
{"TABLE_DATA": {"{table_name}": {"{key}": "{value}"}, ...}, ...}to set table specific data. This data will be available in the custom SQL templates e.g.SELECT {{key}}. - Auto QA Deduplication Table Mapping: Mapping between the tables that store append-only data and the deduplicated tables. The dedupeTable in mapping will be used for QA scripts. If dedupeSchema is not specified, the deduplicated table will be created in the same schema as the raw table.
- Use Iceberg Table: Specifies whether the connector should write into a pre-existing Snowflake-managed Iceberg table instead of a standard Snowflake table. This is a distinct ingestion mode with its own Snowflake setup and privileges, and cannot be changed after the destination is created. See Iceberg Tables before enabling.
- Use Dynamic Tables: Specifies whether the connector should create Dynamic Tables & Cleanup Tasks. See Dynamic Tables.
-
upsertmode:- Delete Mode: Specifies whether the connector processes deletions (or tombstone events) and removes the corresponding row from the database.
- Use Hybrid Tables: Specifies whether the connector should create Hybrid Tables.
-
Click Save.
Iceberg Tables
Streamkap’s Snowflake Connector can write into a Snowflake-managed Iceberg table instead of a standard Snowflake table. This is enabled with the Use Iceberg Table setting, available in append mode.
Iceberg ingestion is a distinct ingestion mode, not a variation of standard-table ingestion. It has its own Snowflake setup, its own privileges, and its own behaviour — all covered below. Read this section in full before creating an Iceberg destination.
Snowflake setup for Iceberg
This is in addition to the Snowflake Setup above — the warehouse, user, role and network policy are still required. Iceberg then needs three further things.
1. An external volume. Iceberg tables store their data and metadata as open-format files in your own cloud storage, so an external volume must exist and the Streamkap role must be able to use it.
Setting a default external volume on the database or schema is recommended — the connector’s Dynamic Table DDL then inherits it, and no template editing is required.
SET role_name       = UPPER('STREAMKAP_ROLE');
SET database_name   = UPPER('STREAMKAPDB');
SET schema_name     = UPPER('STREAMKAP');
SET external_volume = UPPER('MY_EXTERNAL_VOLUME'); -- your existing external volume

-- Allow the Streamkap role to use the external volume.
-- Run as the role that owns the external volume (ACCOUNTADMIN only if that is the owner).
GRANT USAGE ON EXTERNAL VOLUME IDENTIFIER($external_volume) TO ROLE IDENTIFIER($role_name);

-- Recommended: make it the default so Iceberg DDL can omit EXTERNAL_VOLUME
ALTER SCHEMA IDENTIFIER($schema_name) SET EXTERNAL_VOLUME = $external_volume;
2. Pre-created Iceberg tables. Unlike standard Snowflake tables, Streamkap does not create Iceberg tables. Create one per topic, before starting the connector. Only the metadata column is required — the connector adds the data columns by schema evolution.
CREATE ICEBERG TABLE MY_TABLE (
  record_metadata OBJECT()
)
EXTERNAL_VOLUME = 'MY_EXTERNAL_VOLUME' -- omit if set as the schema default
CATALOG = 'SNOWFLAKE';
The table name must match the name the connector writes to, as determined by your topic-to-table mapping.
3. Ownership of each Iceberg table, and schema evolution enabled on it. Because the tables are created by you rather than by the connector, both of the following are required on every Iceberg table the connector writes to.
-- Give the Streamkap role ownership of the table
GRANT OWNERSHIP ON TABLE MY_TABLE TO ROLE IDENTIFIER($role_name);

-- Enable schema evolution on the table itself
ALTER ICEBERG TABLE MY_TABLE SET ENABLE_SCHEMA_EVOLUTION = TRUE;Both statements must be run for every Iceberg table you create for the connector.
Schema evolution works as it does for standard tables: new columns are added automatically as they appear in the source. Iceberg additionally allows an existing column to be widened in place — for example INT to LONG, or an increase in decimal precision.
Dynamic Tables with Iceberg
Dynamic Tables work with Iceberg, but they are created as Dynamic Iceberg Tables so the deduplicated table also stays in open format in your external volume. Streamkap selects the correct template automatically when Use Iceberg Table is enabled.
A standard Dynamic Table cannot be used over an Iceberg table, because it cannot hold the typed RECORD_METADATA object that Iceberg tables use.
The default template omits EXTERNAL_VOLUME so that it is inherited from the database or schema default. If you have not set a default, edit the Custom SQL Template - Dynamic Table Creation field in the Streamkap UI to add EXTERNAL_VOLUME = '<your volume>'.
Behaviour differences vs. standard tables
- Tables are not auto-created. They must exist before the connector starts (see above).
- JSON-sourced columns are written as plain text rather than a native, queryable
VARIANTcolumn. - Nested or composite source columns (structs, arrays, maps) are written as rigid, fully-typed
OBJECT/ARRAY/MAPstructures rather than a flexibleVARIANTcolumn — every new field or shape requires a schema-evolution event, and values outside the mapped types will cause errors. - Record keys are written to
RECORD_METADATA.keyas text. Composite and structured keys are serialised to JSON. - Numeric and temporal columns behave the same as on standard tables.
For further detail, see Snowflake’s Snowpipe Streaming for Iceberg documentation, which covers additional limitations and caveats on the Snowflake side.
Troubleshooting
Dynamic Tables
Snowflake Dynamic Tables are materialized views which consist of the latest records inserted into Snowflake. Streamkap’s Snowflake Connector creates them—if enabled—for each table the first time a record is streamed for them. They refresh themselves according to their TARGET_LAG. Below is the default template—shown in the Streamkap UI. You can modify it there to suit your requirements.
  CREATE OR REPLACE DYNAMIC TABLE {{table}}_DT
    TARGET_LAG = '15 minutes' -- Minimum is 1 minute
    WAREHOUSE = {{warehouse}}
    AS
  SELECT * EXCLUDE dedupe_id
  FROM (
    SELECT *,
      ROW_NUMBER() OVER (
        PARTITION BY {{primaryKeyColumns}}
        ORDER BY _streamkap_ts_ms DESC, _streamkap_offset DESC
      ) AS dedupe_id
    FROM {{table}}
  )
  WHERE dedupe_id = 1         -- Latest record
    AND __deleted = 'false';  -- Excluding deleted records

  CREATE OR REPLACE TASK {{table}}_CT -- This statement and the `ALTER TASK {{table}}_CT RESUME;` can be removed if you don't want to clean up old records
    WAREHOUSE = {{warehouse}}
    SCHEDULE = '4380 minutes' -- We don't recommend changing this to a very short interval (e.g. 30 minutes) as it can increase Snowflake costs
    TASK_AUTO_RETRY_ATTEMPTS = 3
    ALLOW_OVERLAPPING_EXECUTION = FALSE
    AS
  DELETE FROM {{table}}
  WHERE NOT EXISTS (
    SELECT 1
    FROM (
      SELECT {{primaryKeyColumns}}, MAX(_streamkap_ts_ms) AS max_timestamp
      FROM {{table}}
      GROUP BY {{primaryKeyColumns}}
    ) AS subquery
    WHERE {{{keyColumnsAndCondition}}}
      AND {{table}}._streamkap_ts_ms = subquery.max_timestamp
  );

ALTER TASK {{table}}_CT RESUME;Offset Management (Append Mode)
Understanding Dual Offset Tracking
When using append mode with Snowflake destinations, there are two, separate offset systems to manage:
-
Consumer Group Offsets (
connect-{connector-id})- Tracks which messages the connector has consumed from the source topic
- Visible in Streamkap UI under Consumer Groups
-
Snowflake Channel Offsets
- Tracks which messages have been successfully ingested into Snowflake via Snowpipe Streaming
- Each topic partition creates a Snowflake channel (e.g.,
TOPIC_0for partition 0) - Managed within Snowflake using
SYSTEM$SNOWPIPE_STREAMING_UPDATE_CHANNEL_OFFSET_TOKEN
Replaying Messages to Snowflake
To replay messages (resend data to Snowflake), you must coordinate resets across both offset systems:
Before you start:
- Ensure you have the required Snowflake privileges (e.g., OWNER on the table)
- Note the offset position you want to replay to (earliest, specific offset, or timestamp)
- Plan for the replay window within your topic retention period
Step 1: Stop the Destination Connector
In Streamkap UI, navigate to the connector and click Stop or Pause.
Wait for the connector status to show as stopped. This prevents Snowpipe Streaming from committing offsets while you reset them.
Step 2: Reset Consumer Group Offsets
Use Streamkap UI to reset the consumer group:
- Go to Consumer Groups
- Find the consumer group for the destination connector (e.g.
connect-{connector-id}) - Follow the Consumer Groups Reset Procedure to reset to your desired position
Step 3: Reset Snowflake Channel Offsets
Connect to Snowflake (using your preferred client: SnowSQL, DBeaver, or Snowflake web UI) and reset each channel to -1. This tells Snowflake to defer to the Consumer Group offset position.
-- First, view current channels and their offsets
SHOW CHANNELS IN SCHEMA <database>.<schema>;

-- For each channel, reset the offset to -1
-- Replace <DATABASE>, <SCHEMA>, <TABLE_NAME>, and <TOPIC_NAME_0> with your actual values

SELECT SYSTEM$SNOWPIPE_STREAMING_UPDATE_CHANNEL_OFFSET_TOKEN(
    '<DATABASE>.<SCHEMA>.<TABLE_NAME>',
    '<TOPIC_NAME_0>',  -- Channel name (usually TOPIC_PARTITION_NUMBER, e.g., ORDERS_0, ORDERS_1)
    '-1'               -- Reset to -1 so Snowflake uses the Consumer Group offset
);
Example: Reset channel to use Consumer Group offset
-- Reset topic "orders" partition 0 to use Consumer Group offset
SELECT SYSTEM$SNOWPIPE_STREAMING_UPDATE_CHANNEL_OFFSET_TOKEN(
    'MY_DB.MY_SCHEMA.ORDERS_TABLE',
    'ORDERS_0',
    '-1'
);

-- Repeat for each partition (ORDERS_1, ORDERS_2, etc.)Step 4: Resume the Destination Connector
In Streamkap UI, click Resume or Start on the connector.
Step 5: Verify the Replay
Monitor the connector and destination table to confirm:
- Connector status shows as active/running
- Consumer lag decreases as messages are re-ingested
- Data appears in the destination table
Offset Reset Strategies
The offset position is controlled by the Consumer Group. When resetting offsets, choose one of the following strategies in Streamkap UI (see Consumer Groups Reset Procedure):
| Strategy | Description | Use Case |
|---|---|---|
| Earliest | Reset to the beginning of the partition | Replay all available messages within retention window |
| Latest | Reset to the end of the partition | Skip all existing messages and start fresh |
| Specific Timestamp | Reset to the first offset after a given timestamp | Replay messages from a specific point in time |
| Specific Offset | Set a custom offset position | Precise control over where to resume |
After resetting the Consumer Group offset to your desired position, reset the Snowflake channel offset to -1 so it defers to the Consumer Group position:
SELECT SYSTEM$SNOWPIPE_STREAMING_UPDATE_CHANNEL_OFFSET_TOKEN(
    '<DATABASE>.<SCHEMA>.<TABLE_NAME>',
    '<TOPIC_NAME_0>',
    '-1'
);
Upsert mode
Snowflake destination connector can run in upsert mode. This mode switches off the use of snowpipe streaming and connector uses periodic MERGE INTO statements to upsert data into target snowflake tables. Dynamic tables or other de-duplication mechanisms will not be necessary when using upsert mode.
Getting the Snowflake URL
You can also run the script below in a Snowflake worksheet to return the Snowflake URL. You need to be logged into Snowflake with an account granted ORGADMIN system-defined role to run this script.
USE ROLE ORGADMIN;

-- Snowflake URL is the 'account_url', not 'account_locator_url'
SHOW ACCOUNTS;
Snowflake Setup scripts failing
There can be many reasons for them to fail, but the scripts below can help you diagnose the issues.
You need to be logged into Snowflake with an account granted ACCOUNTADMIN system-defined role or custom role with equivalent privileges to run these scripts.
Copy paste the scripts below into Snowflake worksheets. Change the object names at the top as required and run all queries.
-- Replace object names below with the names used by your Snowflake Setup script
SET warehouse_name      = UPPER('STREAMKAP_WH');
SET database_name       = UPPER('STREAMKAPDB');
SET schema_name         = UPPER('STREAMKAP');
SET role_name           = UPPER('STREAMKAP_ROLE');
SET user_name           = UPPER('STREAMKAP_USER');
SET network_policy_name = UPPER('STREAMKAP_NETWORK_ACCESS');

-- If your Snowflake account uses custom roles to grant privileges, change the role name below
SET accountadmin_role   = UPPER('ACCOUNTADMIN');

USE ROLE IDENTIFIER($accountadmin_role);

-- If any of the queries fail or return no results, '$accountadmin_role' doesn't have necessary privileges, or the object doesn't exist
-- Warehouses, databases and schemas
DESC WAREHOUSE IDENTIFIER($warehouse_name);
DESC DATABASE IDENTIFIER($database_name); -- Displays schemas; no need for DESC SCHEMA ... query also

-- Users
DESC USER IDENTIFIER($user_name); -- Shows name, defaults and RSA details; no need for separate queries

-- Network policies
DESC NETWORK POLICY IDENTIFIER($network_policy_name);
-- Replace role name below with the role name used by your Snowflake Setup script
SET role_name = UPPER('STREAMKAP_CONNECTOR');
-- If your Snowflake account uses custom roles to grant privileges, change the role name below
SET accountadmin_role = UPPER('ACCOUNTADMIN');
USE ROLE IDENTIFIER($accountadmin_role);
-- List privileges
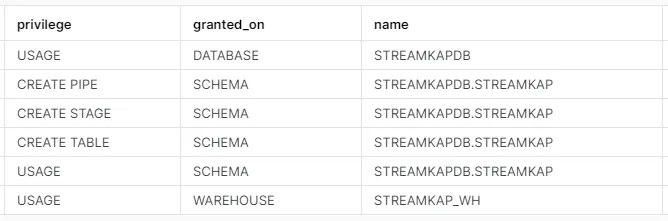
SHOW GRANTS TO ROLE IDENTIFIER($role_name);If any of the queries return an error or no results:
- Check in the top right corner (next to Share and Run buttons) of the Snowflake Worksheets that the role is set to
ACCOUNTADMIN, or a custom role with equivalent privileges - Depending on which query failed or returned no results, check the object names at the top of the script are correct
- If a query returns
"Object does not exist or is not authorized"error, go to the Snowsight UI Admin page and see if the object is showing there. For example, ifDESC WAREHOUSE ...failed, go to Admin -> Warehouses page and check if the Warehouse is shown on that page
If the warehouse, database, schema, role and user exists, privileges might be an issue. Run Script #2 and ensure the privileges displayed match or include the following:
Troubleshooting Common Issues
503 / NullPointerException errors
Transient Snowflake Streaming API overload. Do NOT restart the connector — the built-in retry mechanism with exponential backoff handles recovery automatically, typically within 5-30 minutes.
If the error persists beyond 30 minutes, contact Streamkap support.
Records going to DLQ (16 MB limit)
Snowflake has a maximum record size of 16 MB. Records exceeding this limit are routed to the dead letter queue (DLQ).
Resolution:
- Identify the oversized columns in the DLQ message payload
- Exclude large columns from replication if they are not needed at the destination
- Add a transform to truncate large fields before they reach the destination
VARCHAR overflow — column value exceeds size
When a source column value exceeds the VARCHAR size defined at the destination, the record is routed to the DLQ.
Resolution:
- Increase the column size at the destination:
ALTER TABLE ... ALTER COLUMN ... TYPE VARCHAR(n) - Configure a transform (SMT) to truncate values before delivery if increasing the column size is not feasible
Schema Evolution Permissions
Streamkap’s Snowflake connector supports schema evolution – automatically adding new columns to destination tables when the source schema changes. For this to work, the Snowflake role used by the connector must have the correct privileges on the target tables.
Related Documentation
- Ingestion Modes - Understand insert vs. upsert ingestion modes
- Delete Handling - Configure how delete events are processed at the destination